Platform Primitives That Make Every-User Agent Persistence Operationally Viable at Scale
Reduce idle compute costs by freezing agent state into storage instead of running persistent VMs.
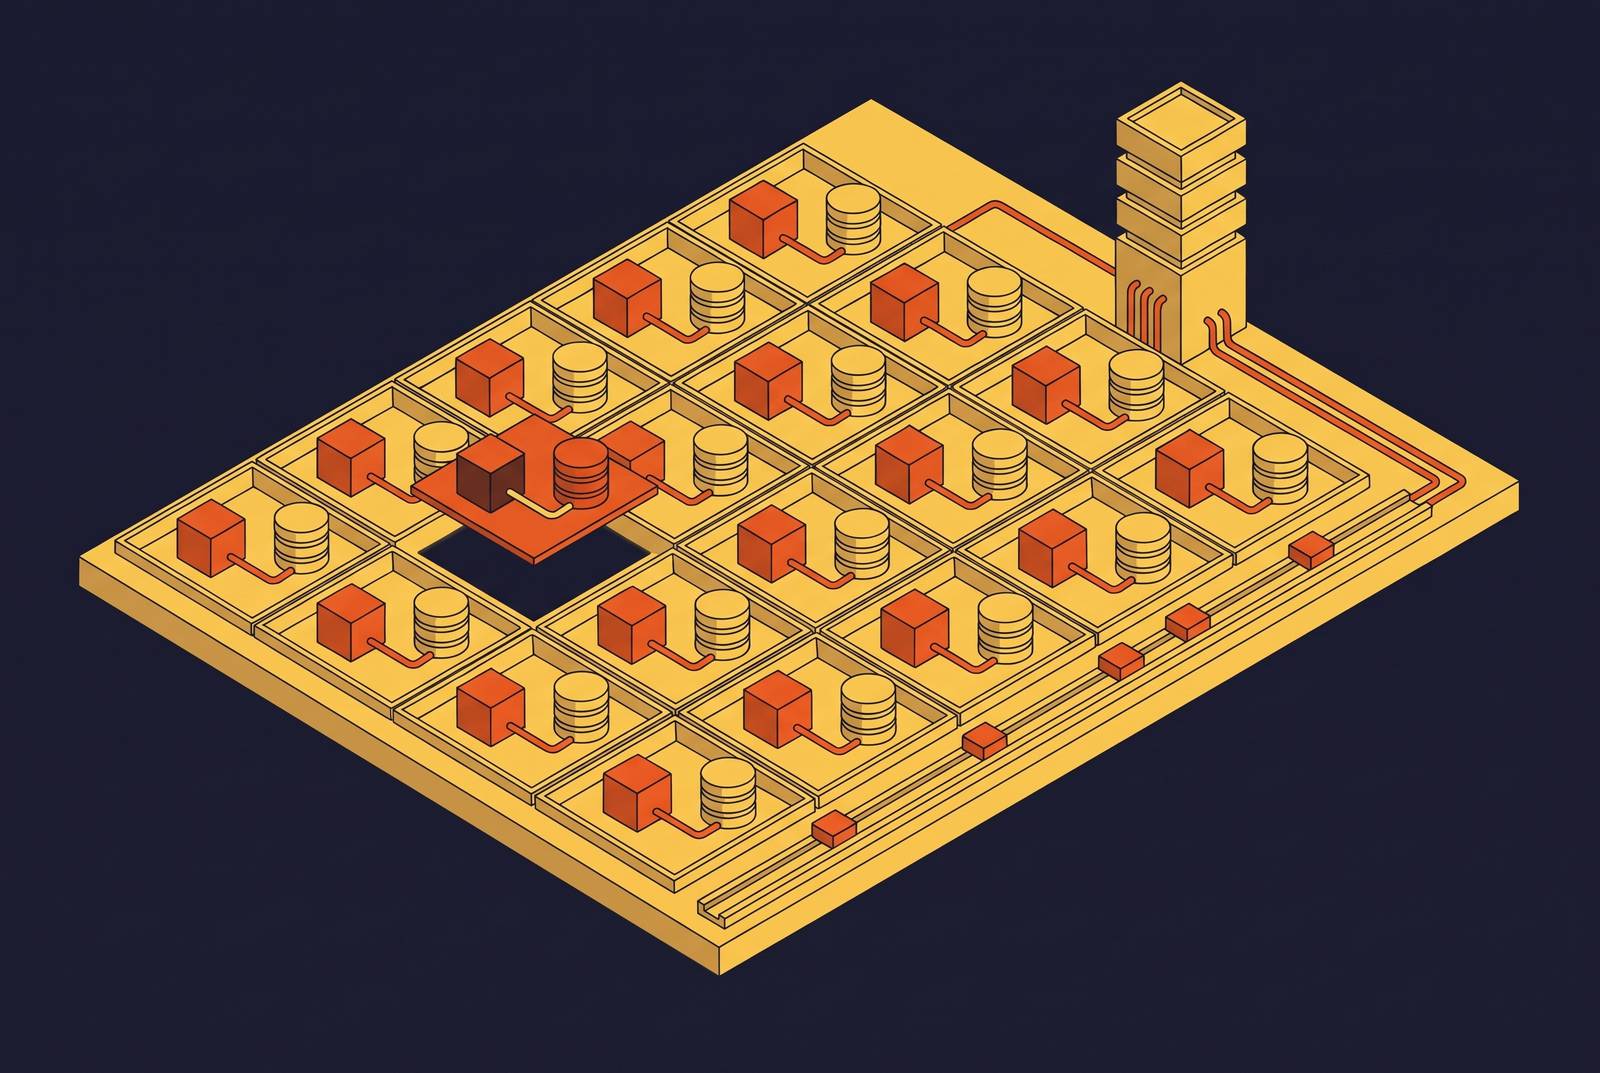
Per-user persistent AI agent deployment at scale requires three platform primitives working together, namely micro-VM isolation, snapshot-restore scheduling, and thin CLI, SDK, and MCP tooling. Together, they make dedicated execution safe, turn idle compute into stored state, and take the manual work out of each deployment’s lifecycle. Persistent memory needs its own design, because resuming an agent’s execution does not by itself give that agent knowledge it can trust across sessions.
Why the every-user agent model breaks under conventional infrastructure
A dedicated agent must retain more than a conversation. Each user’s agent has its own state, credentials, memory, and unfinished tasks, all of which must survive gaps between interactions. Those gaps dominate the workload. Most agents are waiting on a user, a tool response, a human approval, or an asynchronous process. Provisioning an always-on VM for every agent therefore ties expenditure to registered users.
Stateless execution avoids that standing compute bill but does not supply continuity. LLMs are stateless by design, and replaying full conversation histories produces rising latency, buried facts, and expanding token costs. Long context is not a persistence strategy. Infrastructure consequently extends beyond model pricing, because the execution harness controls waiting costs and the survival of unfinished work. Fleet-scale persistence requires micro-VM isolation, snapshot-restore scheduling, and thin tooling to operate as one platform.
Why micro-VM isolation is the right execution boundary for agents, not containers and not bare serverless functions
Agents that install packages, execute arbitrary code, and keep credentials need an execution boundary that can safely contain what they are allowed to do. Containers share the host kernel across tenants, so a kernel vulnerability reachable from one container can threaten the host and its other containers. Firecracker runs a separate virtual machine monitor process for each microVM rather than one daemon managing every VM, giving each workload its own isolated process and guest kernel.
That separation is useful only if its overhead permits dense deployment. The Firecracker project reports that each microVM has reduced memory overhead of less than 5 MiB, with sub-second boot times, high density per host, and greater than 95% of bare-metal CPU performance. These specifications show that VM-level isolation can work at near-container density. They establish that the isolation boundary itself can use a small per-agent allocation. Its brief startup delay is also small against LLM inference measured in seconds.
The execution environment provides capabilities that bare stateless functions do not. An agent can use a persistent disk that survives sleep and redeployment, install and rebuild its packages, and retain browser sessions or long-running processes past a function timeout. The guest kernel belongs to its environment. However, an always-on fleet of microVMs still incurs idle compute charges, so isolation alone cannot make that fleet economical.
How snapshot-restore scheduling converts idle agents from compute line items into storage line items
Snapshot-restore scheduling separates an agent’s continued existence from a running allocation of compute. The platform boots a microVM, freezes its state into a snapshot, stores that snapshot, and terminates the running instance. A later request restores the saved environment. During the gap, storage replaces active compute.
A warm pool makes the opposite trade. Its VMs remain running to provide immediate handoff, whether or not requests arrive. That can reduce handoff latency, but it preserves the idle bill that dominates a mostly inactive agent fleet. Snapshot restore instead incurs a warm-start delay. The memory needed between resume and readiness is the working set of pages the guest actually touches.
AWS builder content on Lambda MicroVM rates illustrates the resulting cost difference. Running the VM for a short time and then suspending it for hours costs far less than keeping the same VM running throughout, while storing snapshots for a thousand dormant tenants costs tens of dollars a month. Idle cost remains small. This distinction gives “near-zero idle cost” a useful meaning without suggesting that snapshots are free or that active execution has no charge.
Durable-execution harnesses apply the same principle above the VM layer. When an agent waits for approval, a tool response, or an asynchronous event, the harness can persist execution state and terminate the process until a trigger resumes it. The choice of harness therefore changes costs even when the model stays the same. Step-level checkpointing also allows recovery without replaying completed workflow steps, although side-effecting nodes must be idempotent because resumption does not provide exactly-once semantics. None of this removes the provisioning, identity, deployment, and tool-registration work associated with thousands of agents.
Why persistent memory architecture must be a deliberate design decision, not an afterthought bolted onto the execution layer
Before that operational work can be abstracted, the platform must distinguish execution persistence from memory. State records the agent’s current position, including its workflow step, last tool output, and tracked variables. Memory carries information from one turn, session, or agent execution to another. These solve different failures. Broken state interrupts a task, while broken memory prevents reliable personalization and reuse of knowledge even when the task runner resumes correctly.
The working buffer is not an adequate substitute for that architecture. Beyond the cost and latency of raw conversation replay, conflicting versions of a fact can coexist in the context window without any guarantee that the model selects the current one. Summarization introduces another tradeoff. Compressing older turns can reduce tokens but may rewrite the prompt prefix, invalidate the KV cache, and cause a latency spike on the next call. Managing prompt length therefore does not settle the question of what the agent knows.
Semantic memory addresses that question through facts, preferences, and domain knowledge extracted asynchronously into an external queryable store, typically a vector store with metadata filtering. The information that fits the task is retrieved and added to the prompt before the model gets it. Versioning is essential when a user changes a preference. Appending the new statement without resolving the old one leaves the conflict intact. Episodic memory keeps records of task attempts, outcomes, and failures so the agent can draw on them in later work.
Checkpointing connects these memory decisions to resumable execution without making every object durable. Open file handles and client objects cannot be treated as checkpointable workflow state, which constrains what belongs in a saved graph node. Persistent storage is not universal serialization. The VM supplies an environment and disk, while the memory architecture supplies continuity of knowledge independent of any single snapshot. Even with that separation correctly designed, each agent still needs provisioning, identity, and tool configuration unless the tooling layer absorbs that work.
How thin tooling layers — CLI, SDK, and MCP — collapse the operational surface per agent toward zero
A fleet becomes operationally tractable when adding agents stops adding manual procedures. Each agent needs an identity, registered tools, a deployment target, and a way to be updated and observed. The tooling layer must express them as reusable platform operations so that the ten-thousandth deployment requires no more human attention than the first.
The Model Context Protocol gives agents a common interface for connecting to tools. The July 2026 MCP specification update removed protocol-level sessions and the initialize handshake, making each request self-contained. Requests can go to any server instance behind a plain round-robin load balancer without shared session state. That removes per-connection affinity from the transport. At fleet scale, agents can call registered tools from different VM instances without tying those calls to sticky sessions or per-instance configuration.
Runtime discovery extends that abstraction to finding tools. An agent can query a discovery server for candidates, trust signals, and client-specific configuration. Deployment remains a separate concern. A single CLI command should create the VM, attach storage, register identity, configure tools, and expose an endpoint. The SDK should then handle snapshot, restore, wake, and sleep so that application code does not directly manage VM lifecycle.
Thin tooling must also avoid turning initialization into another distributed workflow. Google ADK requires production agents to define McpToolset synchronously in agent configuration, reserving dynamic asynchronous initialization for local debugging or custom standalone runners. That rule expresses a useful boundary. Deployment configuration should be declarative and synchronous, while tool discovery can remain dynamic at runtime. Otherwise, the abstraction meant to take work away adds its own deployment-time dependencies and ways for deployment to fail.
How the three primitives interlock, and why each is necessary but none is sufficient alone
The three primitives must compose across the agent lifecycle. Isolation defines which environment and credentials belong to a tenant. Scheduling determines when that environment consumes compute. Tooling coordinates provisioning and the transition between active execution and stored state.
Snapshotting a shared-kernel container does not create a VM-level boundary, and restoring it into a shared environment retains cross-tenant state risks. Scheduling cannot repair an inadequate security boundary. Without snapshot restore, even a secure fleet pays compute rates while agents wait. Low virtualization overhead reduces the size of that charge but does not change its relationship to idle time.
Removing tooling creates a different failure. Correct isolation and inexpensive suspension remain infrastructure components that developers must coordinate themselves, with provisioning, identity, and tool registration growing with agent count. The SDK and CLI turn those components into repeatable operations, while MCP gives restored instances a common way to reach tools. Memory architecture is still needed alongside them, because an environment that resumes must retrieve the right knowledge as well as recover old execution state.
The build-versus-platform decision therefore concerns the whole operating system around the agent. Integrating Firecracker, a snapshot scheduler, an SDK, a CLI, an MCP server, and an identity layer is a substantial infrastructure project. Utilization changes the economic comparison. Managed platforms can amortize that investment across tenants, which is especially relevant for mostly dormant fleets, while sustained high utilization can make self-hosting worth evaluating. Choosing a different operator does not remove any of the required primitives.
How do developers deploy thousands of persistent agents without rebuilding infrastructure?
Does each agent get an isolated execution environment, or does it share kernel or process space? Does idle time incur compute charges or snapshot storage charges? Can the fleet be provisioned, configured, and deployed through a CLI or SDK without direct VM management?
Managed platforms designed around this architecture offer a path that avoids building the isolation, scheduling, and tooling layers from scratch. The concrete evaluation criteria include the Firecracker micro-VM layer, snapshot-restore scheduler, pricing model, and CLI/SDK deployment surface. A flat-rate plan should be judged against how much time the fleet spends active and dormant, since the rate alone does not show how well scheduling works.