Why Serverless Execution Boundaries Break Multi-Step Agent Workflows
Timeouts, cold starts, and stateless boundaries break agent reasoning loops mid-execution.
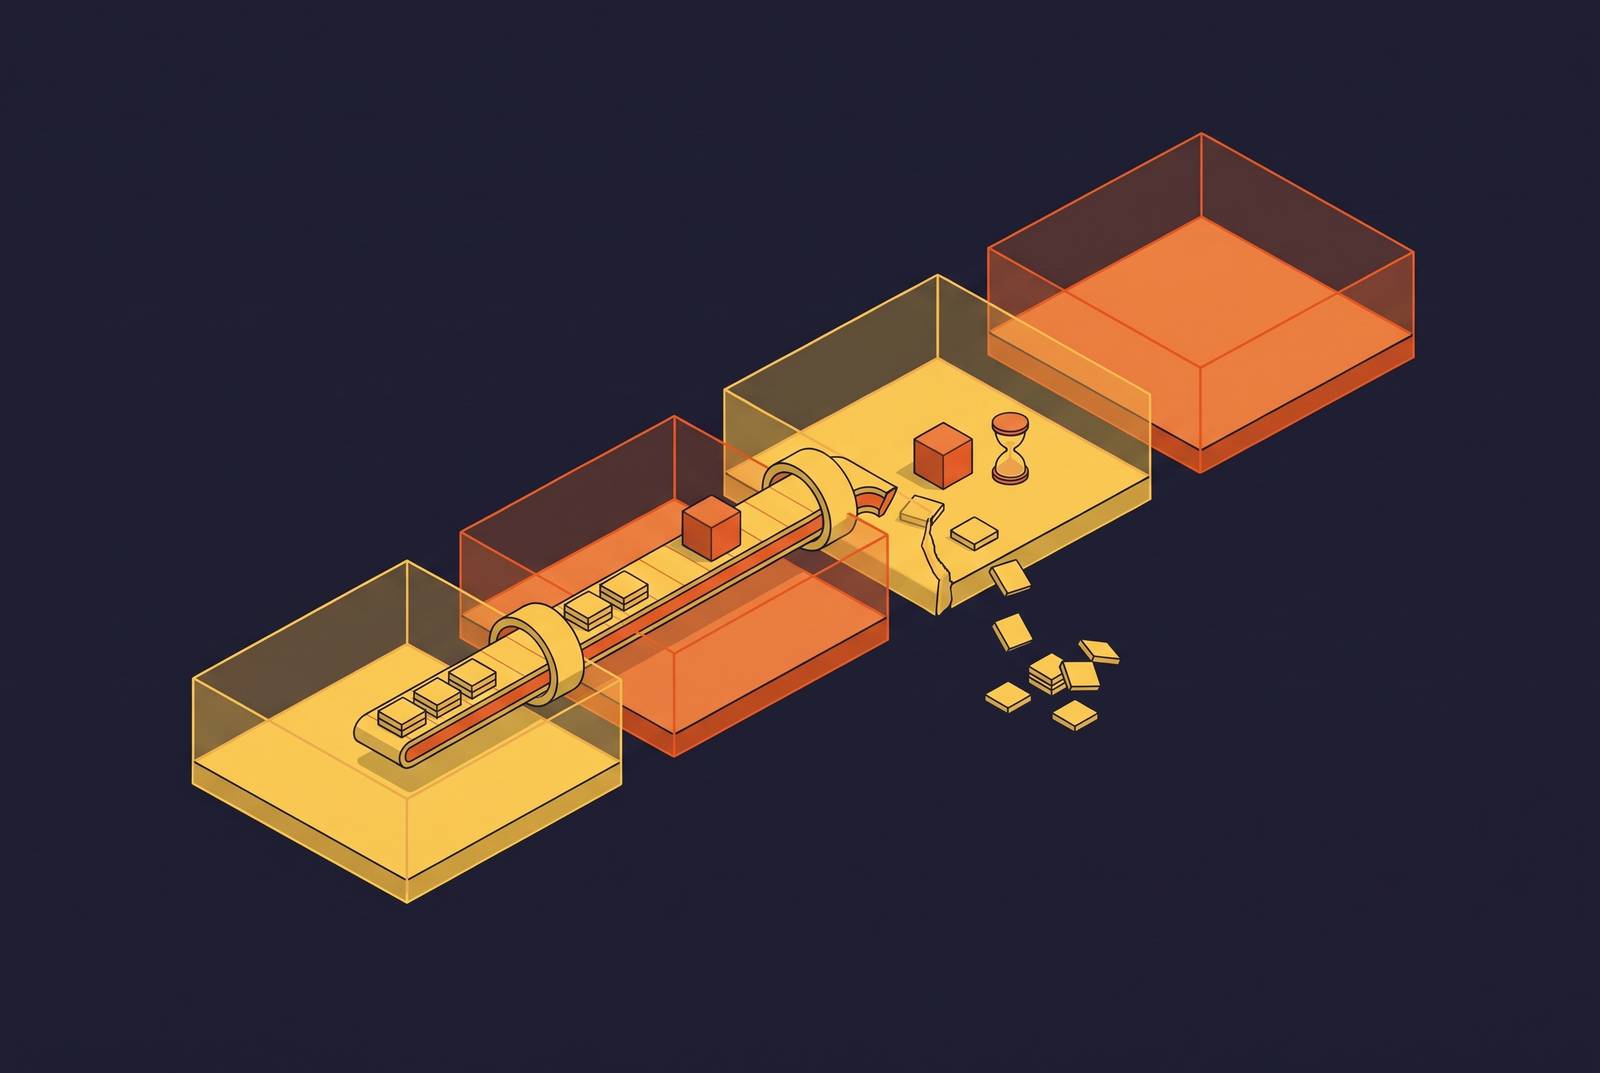
Serverless execution boundaries break multi-step agent workflows when hard timeouts, stateless invocations, and cascading cold starts interrupt a stateful reasoning loop. Persistent AI agent infrastructure fits these workloads better because it preserves the execution environment across work and pauses, while snapshot-restore scheduling avoids paying for idle compute. Serverless functions still work well for short, discrete tasks that can run without keeping a live process.
Why multi-step agents are structurally unlike the workloads serverless was built for
A standard web handler receives a request, queries a database, and returns in milliseconds. Its work fits inside a short invocation. An agent request can instead trigger multiple LLM calls, tool executions, memory retrievals, and parallel subtasks before assembling a response. Each result can change what the agent does next, so the environment must support a stateful loop rather than merely dispatch a predetermined operation.
That distinction separates two broad execution patterns. Predictable task graphs, including prompt chains and planning pipelines, can use discrete invocations because their stages can be set out in advance. Discovery-driven loops, including ReAct and tool-using agents, work better in persistent environments because the path takes shape as they run. Their reasoning chains are still bounded in practice by workflow-level step limits and timeouts.
Agents also do more computation for each request and pause partway through execution while keeping context that the next action needs. A longer timeout can accommodate more work, but it cannot make a stateless invocation preserve a live reasoning process. When both patterns run as ordinary request-response functions, the infrastructure must handle the agent’s normal behavior as exceptions.
How timeout ceilings cut off agent workflows mid-execution
AWS Lambda imposes a maximum execution duration of 15 minutes. Most serverless platforms cap function duration well below it, and increasing a configured timeout cannot remove the platform-enforced stop. When execution reaches that boundary, the function ends regardless of whether the agent has completed its task.
A research agent illustrates the conflict. Searching multiple sources, processing findings, generating a report, and formatting the output can routinely bring a workflow to or beyond Lambda’s limit. ETL jobs, PDF generation, and media transcoding inside agent workflows can also exceed invocation limits during ordinary production work. These operations do not become exceptional merely because an agent initiates them.
Vercel Functions and Cloudflare Workers impose their own caps, although the constrained resource differs. Cloudflare restricts CPU time separately from wall-clock time, so I/O waits do not count toward the CPU allowance, while some invocation types also limit wall-clock duration. That distinction affects which operations exhaust the allowance. It does not provide an unrestricted execution lifecycle.
Moving between platforms therefore changes the execution boundary. A task that fits one platform’s allowance may still fail as its reasoning chain or processing work grows. Splitting the task into shorter invocations is the natural response, but doing so changes what must survive between those invocations.
Why breaking workflows into steps pushes the problem into stateless execution boundaries
Serverless functions do not provide durable continuity for filesystem contents, memory, or in-process context across invocations. The application must reconstruct the context it needs before it can resume useful work. For a multi-step agent, that context includes conversation history, working memory, tool outputs, and workflow position.
Consequently, step decomposition requires explicit state externalization. After each step, the agent must write the necessary state to stores such as DynamoDB, S3, or PostgreSQL, then reload it at the start of the next invocation. Durable orchestration through a service such as AWS Step Functions coordinates those transitions. The application must also handle serialization, checkpoint storage, and recovery from partial failures as it runs.
LangGraph makes this requirement visible. With a durable checkpointer and an appropriate durability mode, it can persist workflow variables, history, and position after each step. Its default behavior or InMemorySaver does not provide that durability. The framework can bridge invocation boundaries, but the durable store supplies the continuity that the runtime does not.
Human approval makes the separation especially clear. An agent may wait seconds or hours, and its state must survive the pause exactly without making the wait expensive. A serverless implementation can support that behavior through an external durable execution layer. However, the resulting system is no longer just a collection of inexpensive functions, and its added state infrastructure is a cost of adapting the workload to the execution model.
How cold starts cascade across dependent stages and amplify latency for agents
A study of resource management for serverless workflows identifies cascading cold starts across dependent stages as an amplifying mechanism in serverless workflows. Each stage may need its own startup before it can do its work. When one stage depends on another, those delays chain together.
A four-step agent chain makes the difference concrete. If each dependent stage cold-starts, the user waits through all four startup penalties as well as the actual reasoning and tool execution. Agent functions also tend to start more slowly than thin handlers because their initialization is heavier. A tolerable delay for one isolated function can therefore become a substantial obstacle to an interactive agent.
Scale-to-zero creates the exposure during quiet periods. When environments return to a cold state, new requests have to wait for startup again, perhaps at several stages of the same request. The cost-saving behavior and the latency penalty share a cause.
Pre-warming, AWS Lambda SnapStart, and provisioned concurrency can reduce the penalty, but their scope and economics differ. SnapStart significantly reduces startup time for supported runtimes without addressing GPU workloads or the dependency structure of a multi-stage cascade. Provisioned concurrency keeps environments warm at the cost of paying for idle capacity. Mitigation can improve responsiveness, but it does not make dependent startup boundaries disappear.
What the compounded failure looks like in production: QoS violations, cost spikes, and engineering debt
Timeouts, state reconstruction, and cold starts interact rather than presenting three independent tuning problems. Shortening invocations creates more boundaries at which the agent must save and reload context. Those boundaries can also add more startup delays. Keeping that chain responsive takes more scheduling or warm capacity, as well as the machinery that preserves state.
The Aquatope research finds that multi-stage serverless applications experience suboptimal performance, resource inefficiency, and high costs to a greater degree than simpler functions. Its findings support the structural distinction between an isolated invocation and a dependent workflow. They show why deeper workflows change how resources must be managed as well as adding more of the same computation.
In production, the compensating stack becomes an operational surface of its own. External state stores, durable orchestrators, pre-warming layers, and checkpoint logic each need monitoring, failure handling, and maintenance. Provisioned concurrency, database charges, and orchestration billing accumulate above the base invocation cost. Latency pressure and QoS violations can therefore arrive together with cost spikes, rather than as a trade-off against a reliably cheap service.
The debt is easy to underestimate early. Workarounds that function at small scale can become harder to operate as traffic grows and more workflows depend on them. By the time the mismatch is evident, the application may rely on several layers built specifically to compensate for its runtime. Infrastructure selection then becomes a migration question.
What infrastructure actually matches how multi-step agents run
A reasoning process needs to run for as long as its task requires, while its filesystem and memory must survive pauses and later sessions. Resumption must return it to a ready state in under a second rather than replaying initialization across dependent stages.
Firecracker micro-VMs give each agent its own kernel through hardware virtualization, placing isolation at the VM boundary rather than sharing a kernel between agent environments. In a persistent deployment, the environment remains available across invocations. Persistence and restoration supply the lifecycle that the workload needs.
Containers address part of the problem by supporting longer-running processes without function timeout limits. They do not, by themselves, preserve memory and execution state across replacement or supply durable multi-step orchestration. Teams still have to manage orchestration, health checks, and scaling policies.
Each end user gets a persistent sandbox that has its own disk, credentials, installed packages, and browser sessions. The environment resembles an apartment rather than a disposable function, because the next visit depends on what remains from the previous one. That fit is useful only if keeping the environment does not require keeping all its compute resources active.
How snapshot-restore scheduling makes persistent micro-VM agents economically viable at scale
Persistence need not mean continuously running compute. Most agents in a fleet are idle much of the time while waiting for a user, a tool call, or human approval. Reserving active resources for every session makes total agent count drive cost. Snapshot-restore scheduling lets capacity follow how many sessions are active at once, while idle sessions keep their state in storage.
The mechanism starts by fully booting a micro-VM once. Its state is then snapshotted to disk and restored on demand, preserving filesystem, memory, and process state. A restore path can return the agent in under a second without reinitializing dependencies or reloading its context.
This changes the economics of a per-user fleet. A host that can run only a small number of peak-sized sandboxes simultaneously can retain hundreds of sessions when most are snapshotted and idle. Active sessions use compute resources, while sleeping sessions still need storage. Compute billing can therefore track active concurrency.
Human-in-the-loop workflows benefit directly from this separation. An agent waiting seconds or hours for approval can sleep without consuming compute throughout the pause, then resume where it stopped. Cheap waiting no longer depends on translating the whole process into externally stored workflow records.
AWS shipped AgentCore Runtime V2 on September 18, 2026, making snapshot-restore available as a managed product. New sessions restore a snapshot of an agent that has already completed startup, with P75 cold start times well under a few seconds for container images from 200 MB to 2 GB. Runtime V2 uses per vCPU-hour and per GB-hour pricing. Its new-session startup figures describe a different operation from resuming an existing agent’s full working state, so those measures should not be treated as interchangeable.
Choosing between persistent AI agent infrastructure and serverless functions
Serverless remains appropriate for stateless event-driven processing, short discrete tasks, unpredictable-traffic webhook handlers, and API glue. Lightweight agents whose request lifecycles last seconds can fit that model. Predictable task graphs can also tolerate discrete invocations when their state transitions are explicit.
Discovery-driven reasoning loops, tool-call chains, and human approval pauses introduce a different requirement. The environment must preserve enough continuity for work to continue after an interruption or between sessions. External stores and durable orchestrators can implement that continuity for serverless functions, but they remain additional infrastructure with their own operational costs.
The practical decision turns on whether the agent needs to pick up where it left off. For agents that do, infrastructure evaluation should prioritize native state persistence, task-length execution, restore latency, and the cost of idle sessions. Those criteria expose costs that invocation pricing alone leaves out. Choosing the runtime around them avoids making a growing layer of compensating tooling the foundation of the agent product.